Freshly unsealed material from The New York Times’ copyright lawsuit against OpenAI and Microsoft has provided a closer look at how news content was allegedly collected and used in the development of AI systems.
The three-year-old legal battle has already become one of the most closely watched copyright disputes involving generative AI. The latest material adds new details around paywalls, large-scale copying, AI-generated search results and the potential impact of the technology on publishers.
However, much of the newly disclosed information comes from arguments made by The New York Times in its court filing, while the underlying exhibits remain sealed. As a result, some of the claims cannot independently be assessed from the publicly available documents.
Credits: Tech Crunch
Microsoft Data Shows Potential Impact on Publisher Traffic
One of the most significant disclosures involves Microsoft’s AI-powered search products.
According to the Times’ filing, internal Microsoft data showed that Copilot’s answer-focused search experience could reduce click-throughs to The New York Times’ website by as much as 93% compared with conventional Bing search.
The finding is important because publishers have traditionally depended on search engines to send readers to their websites. AI-powered search products can instead provide answers directly within the search interface, potentially reducing the need for users to visit the original publisher.
The Times argues that this creates a significant economic concern for news organisations whose businesses depend on audience traffic, advertising and subscriptions.
A January 2024 presentation by Microsoft director of Applied Science Brent Hecht reportedly warned about a potential feedback loop. Publishers could lose incentives to produce original content as traffic declines, while AI systems would simultaneously become increasingly dependent on the material produced by those publishers.
The filing quotes Hecht describing the situation as “an astonishing theft of unprecedented proportions” and “the largest theft of labor in human history”.
OpenAI executive Nick Turley, who leads ChatGPT, is also quoted in the filing. He reportedly described the situation facing publishers as an “existential threat”, arguing that chatbot products could already replace some visits to publisher websites and could become increasingly substitutive as AI systems improve.
Paywalls Become Central to Copyright Dispute
The newly unsealed material also sheds light on one of the central issues in the lawsuit: whether copyrighted content can be used without permission to train AI models under the fair-use doctrine.
US copyright law allows certain unauthorised uses of copyrighted material under fair use, with courts considering factors such as the purpose of the use and its potential impact on the market for the original work.
The Times is using the newly disclosed material to argue that AI systems can directly compete with publishers and potentially damage their businesses.
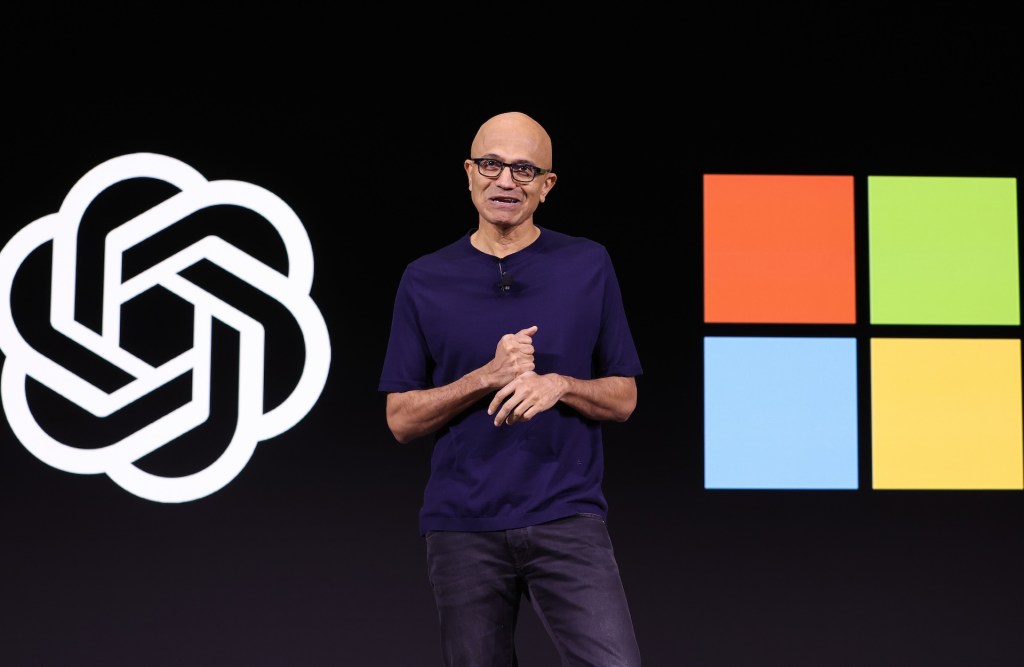
Microsoft CEO Satya Nadella, according to the filing, testified that paywalled material should be licensed when used for AI training or grounding. He also reportedly said Microsoft could have required OpenAI to retrain its models if he had known that paywall-protected material had been scraped and incorporated into training.
The filing also describes an alleged attempt to obtain Times content despite its paywall. Researcher Nick Ryder reportedly told OpenAI president Greg Brockman about a method for bypassing the Times’ paywall, to which Brockman replied, “ah nice.”
Credits: Reuters
Millions of News Documents Allegedly Entered AI Datasets
The filing further highlights the scale of the content allegedly collected for AI training.
The Times says OpenAI’s mid-training datasets contained more than 91,692 copies of works from The New York Times, Daily News and Center for Investigative Reporting.
A separate dataset derived from Common Crawl allegedly contained more than two million documents originating from nytimes.com.
The filing also points to initiatives known as Project Mango and Project Taxi, which allegedly involved exchanges of training material between Microsoft and OpenAI. Project Mango is alleged to have contained copies of at least 160,903 distinct works produced by publishers involved in the litigation.
Another allegation concerns the removal of copyright notices from certain training material before it was incorporated into AI models. According to the filing, the concern was that models could reproduce those notices in their responses.
The newly public material does not establish that OpenAI or Microsoft violated copyright law. Instead, it provides additional evidence that the court may consider while examining the competing arguments over fair use, AI training, market competition and potential harm to publishers.
The case could ultimately help determine how AI companies obtain copyrighted content and what obligations they have toward publishers whose work is used in developing increasingly powerful AI systems.